LensLapse: In-Browser Logit Lens for Interactive Exploration of Language Model Training Dynamics
Nara Institute of Science and Technology (NAIST), Japan
AACL-IJCNLP 2026 · System Demonstrations
Scrub across Pythia's public training checkpoints and watch next-token predictions crystallize from noise into knowledge — layer by layer, with zero backend.
Abstract
The logit lens is a standard mechanistic interpretability tool for inspecting a Transformer's predictions across layers. However, existing logit lens tools typically focus on individual checkpoints rather than interactive exploration of a model's training history.
In this study, we introduce LensLapse, an open-source web application for interactive exploration of a model's training history through token-level interpretability. Users can scrub a slider across public checkpoints from five model families and three multilingual checkpoint suites and observe how per-layer, per-position logit lens predictions evolve from frequency bias to factual knowledge.
For browser-compatible models, arbitrary user prompts are probed live in the browser via local inference over per-checkpoint model pairs. No server, no API key, no hosting cost, and prompts never leave the user's device.
Moreover, LensLapse supports local models. A single pip install enables
users to launch the application and explore their own models and training checkpoints without any
additional web setup.
LensLapse is MIT-licensed and permanently hosted at iamtatsuki05.github.io/lenslapse.
Highlights
A time axis for the logit lens
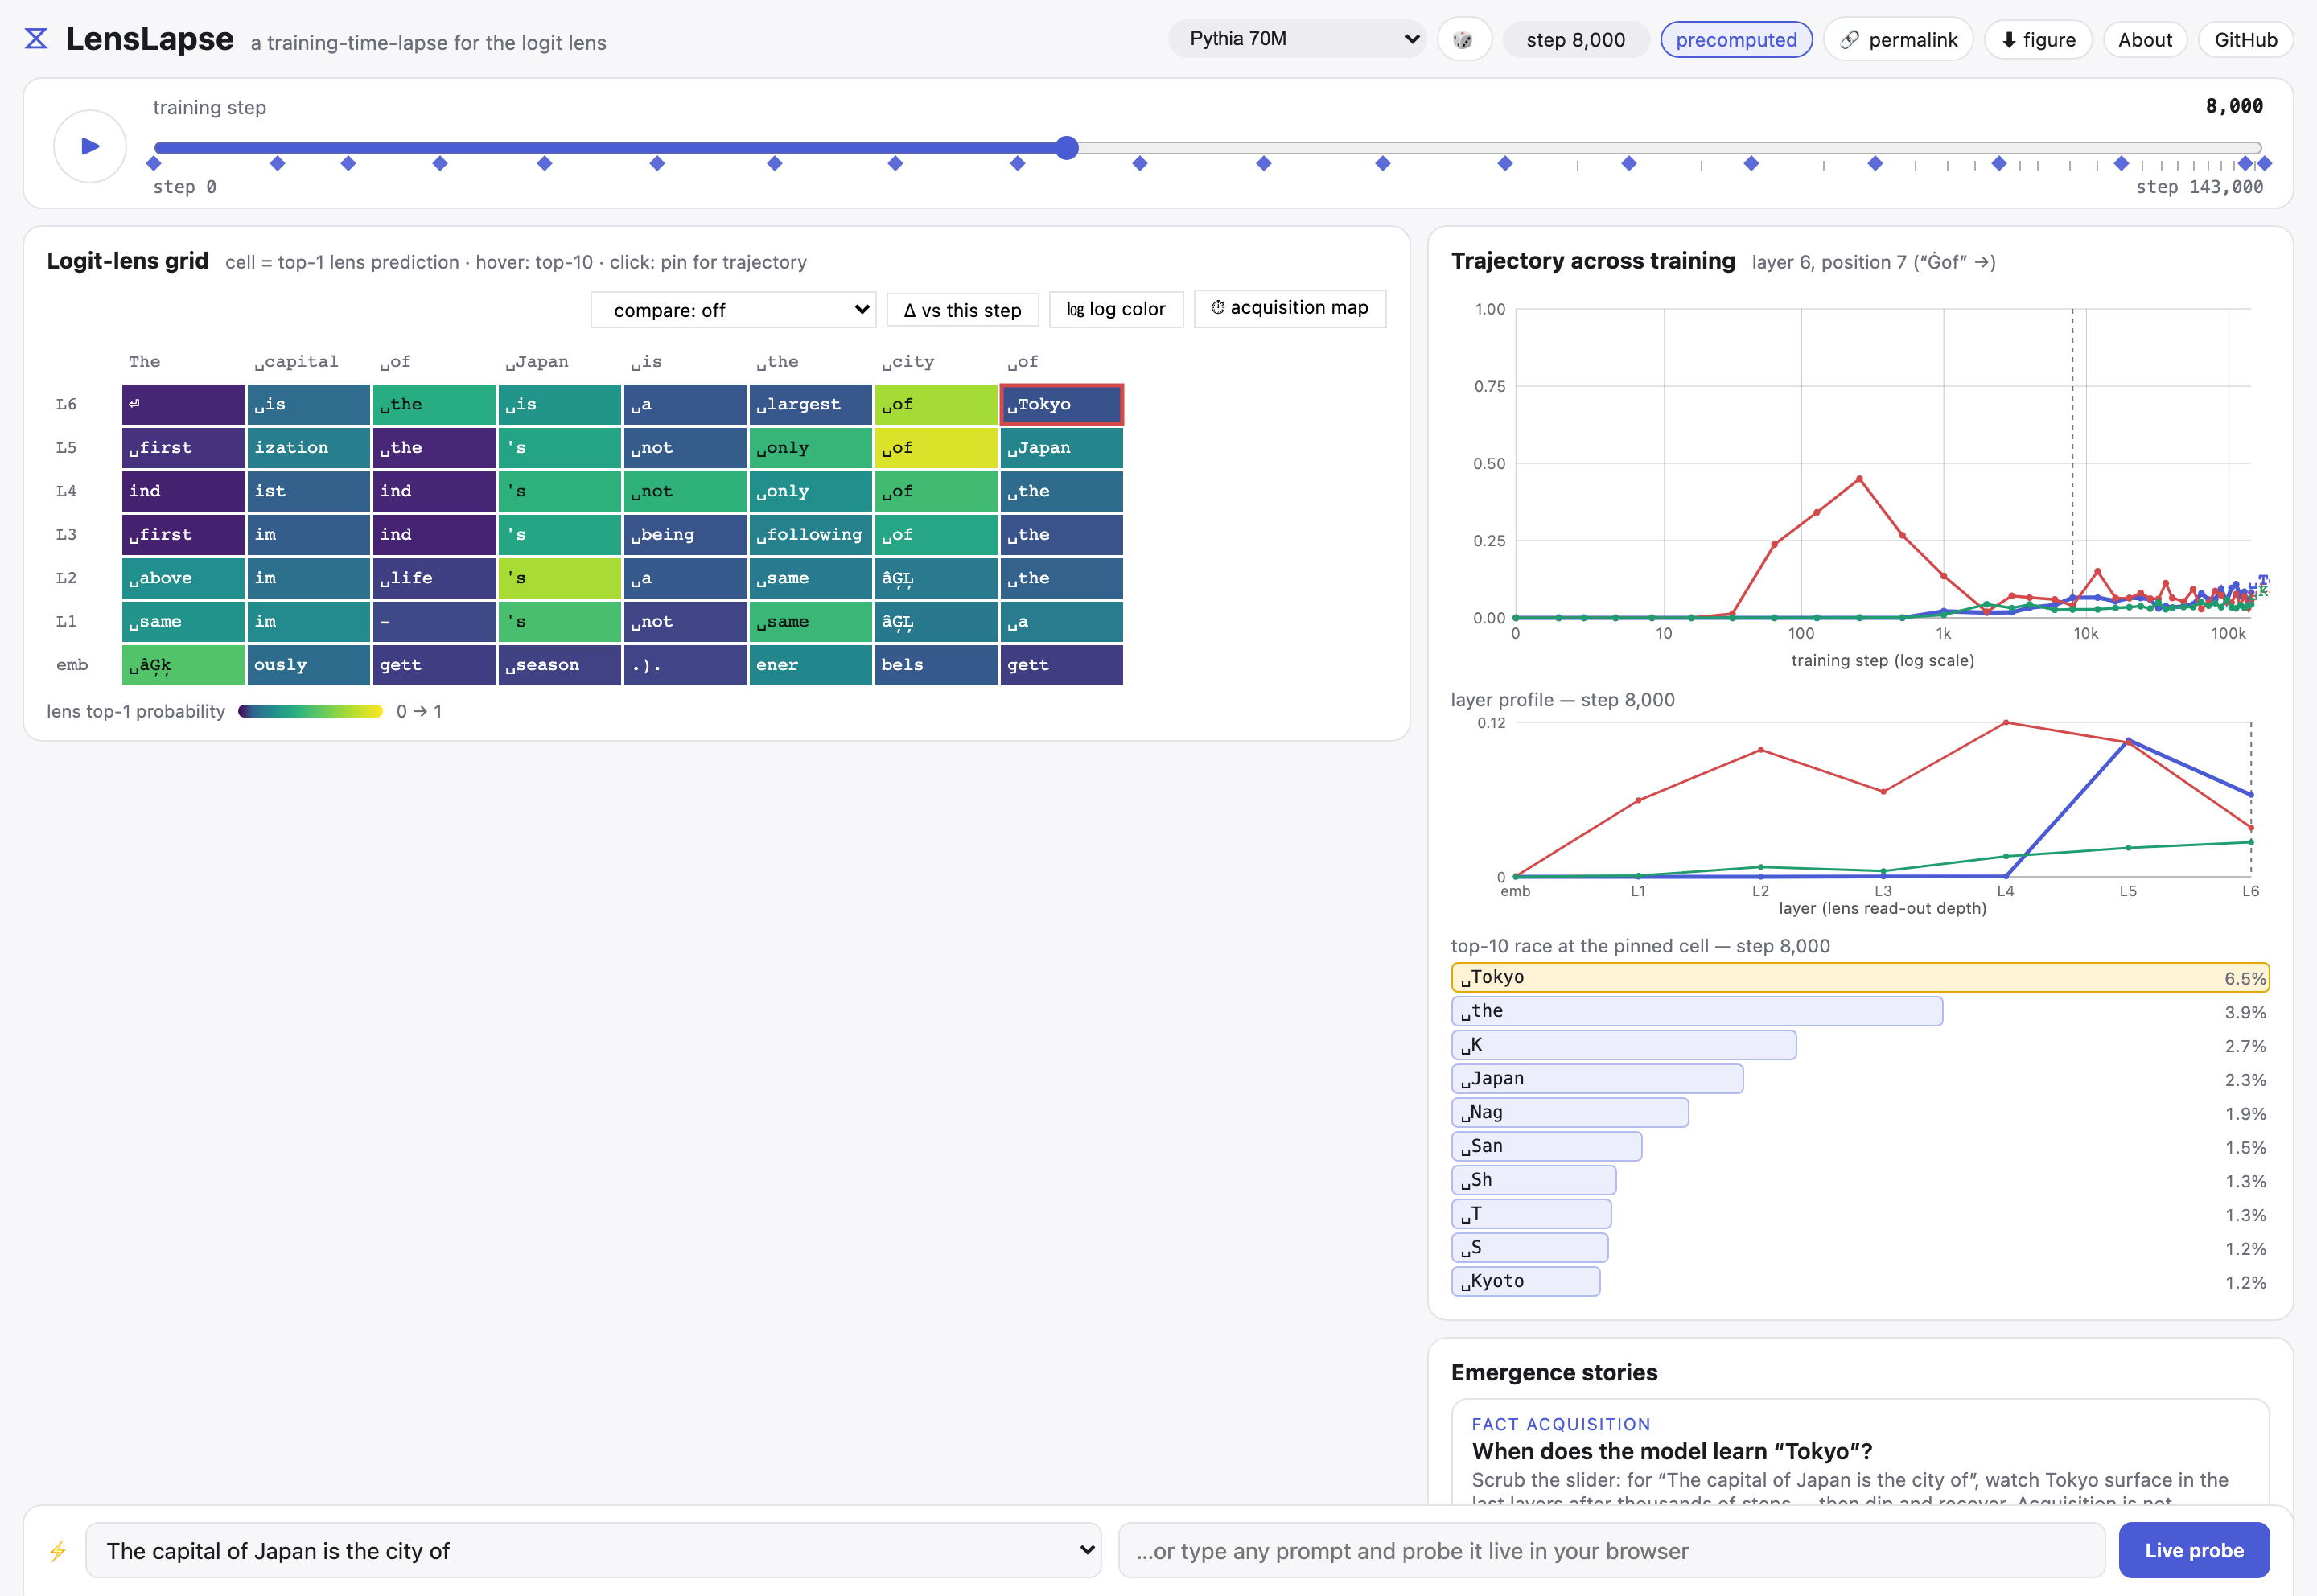
Existing lens tools show one finished model. LensLapse scrubs 38 checkpoints of Pythia-70M (step 0 → 143k) with exact P(token) trajectories — revealing fact acquisition that is visibly non-monotone: learned, lost, and sometimes relearned.
Fully in-browser, zero backend
Free-text prompts run via onnxruntime-web (WebGPU, with WASM fallback) or an optional local probe server — one click probes every checkpoint automatically, so ▶ playback works for anything you type, just like the curated prompts. A static site plus versioned weights on the HF Hub means unlimited concurrent users at zero hosting cost — the demo cannot rot.
Your checkpoints, one pip install
pip install then lenslapse server serves the app and the probe API on one
local port. Point it at any HF model or a local Trainer run — no ONNX conversion, no config files. The
recipe is architecture-generic: GPT-NeoX and GPT-2-style LayerNorm models, plus Llama-style,
Mistral-style, and Gemma-style (plus-one-weight) RMSNorm models, all pass the parity check —
shipped for MAP-Neo, Aquila, BLOOM, SmolLM2, Qwen3, OPT, and Gemma 3 alongside Pythia and GPT-2.
A layout the generic heuristic can't reach registers an explicit override in one line, with no
change to the resolver itself.
Fidelity you can verify
By construction, lens(hL) equals the model's logits — asserted per checkpoint at export. fp16 weight storage keeps 100% top-1 agreement with fp32 PyTorch on our evaluation suite; dynamic int8 drops to 52%, so we do not ship it.
Watchable by design
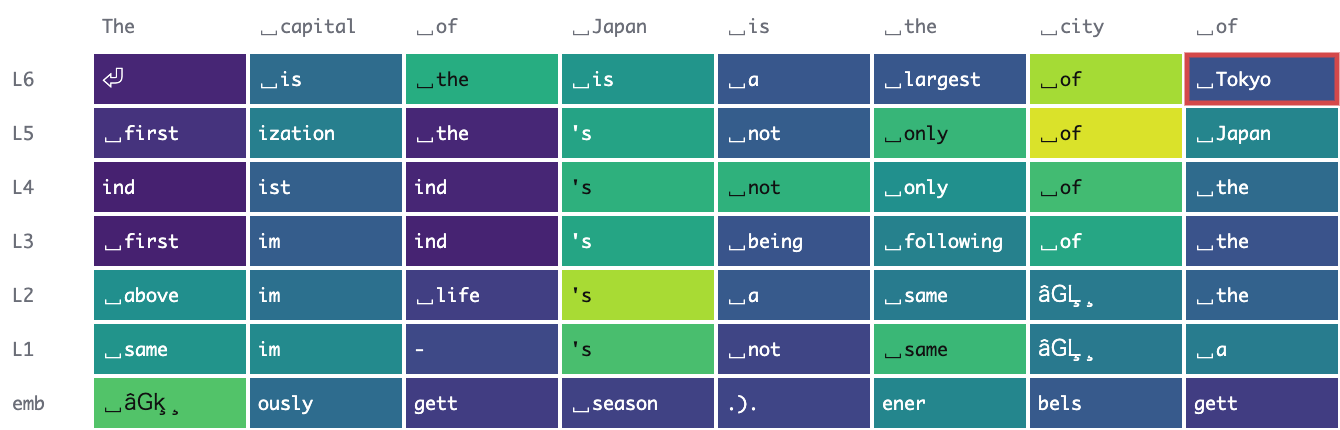
One click plays the whole time-lapse, cells flashing as their top-1 changes. A top-10 bar race and the classic p-vs-layer profile animate at the pinned cell; an acquisition map shows when each cell first learned its final answer, a diff view shows what changed since any reference checkpoint, and a compare mode renders a second model in lockstep — falling back to a live probe of its own when the compared model has no precomputed match for the prompt.
Scriptable end to end
The core actions have CLI twins — lenslapse probe/trace/models —
and the app can copy the exact CLI or cURL command that reproduces the current view. Track any token
across training, share permalinks, or embed a live grid anywhere with ?embed.
Screenshots
How it works
Each checkpoint is exported once into a pair of ONNX graphs: a backbone that returns the pre-layer-norm residual stream after the embedding and every block, and a small lens head (final layer norm + unembedding) applicable to any layer's hidden state. Curated prompts are precomputed with fp32 PyTorch into static JSON shards; a live prompt is tokenized once and then probed against every checkpoint in turn — one forward pass each, pushing every (layer, position) hidden state through the lens head in a single batched matmul — so the same time-lapse playback works for it too. Weights are stored fp16 and cast to fp32 at session load.
Pythia checkpoint (HF Hub, revision step{N})
   ├─ backbone.f16.onnx   input_ids → hidden states [L+1, T, H]
   ├─ lens.f16.onnx       hidden [N, H] → logits [N, V]
   └─ precompute          → static JSON shards (top-10 per cell + trajectories)

browser (static site, no backend)
   ├─ precomputed mode: JSON shard → canvas grid + SVG trajectories
   └─ live mode: onnxruntime-web (WebGPU → WASM) + transformers.js tokenizer
BibTeX
@inproceedings{okada-etal-2026-lenslapse,
    title = "{L}ens{L}apse: In-Browser Logit Lens for Interactive Exploration of Language Model Training Dynamics",
    author = "Okada, Tatsuki  and
      Sakai, Yusuke  and
      Watanabe, Taro",
    editor = "Zhang, Ningyu  and
      Wijaya, Derry",
    booktitle = "Proceedings of the 15th International Joint Conference on Natural Language Processing and the 5th Conference of the {A}sia-Pacific Chapter of the {A}ssociation for {C}omputational {L}inguistics: System Demonstrations",
    month = nov,
    year = "2026",
    address = "Hengqin, China",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2026.aacl-demo.9/",
    pages = "66--73",
    ISBN = "979-8-89176-441-5"
}